
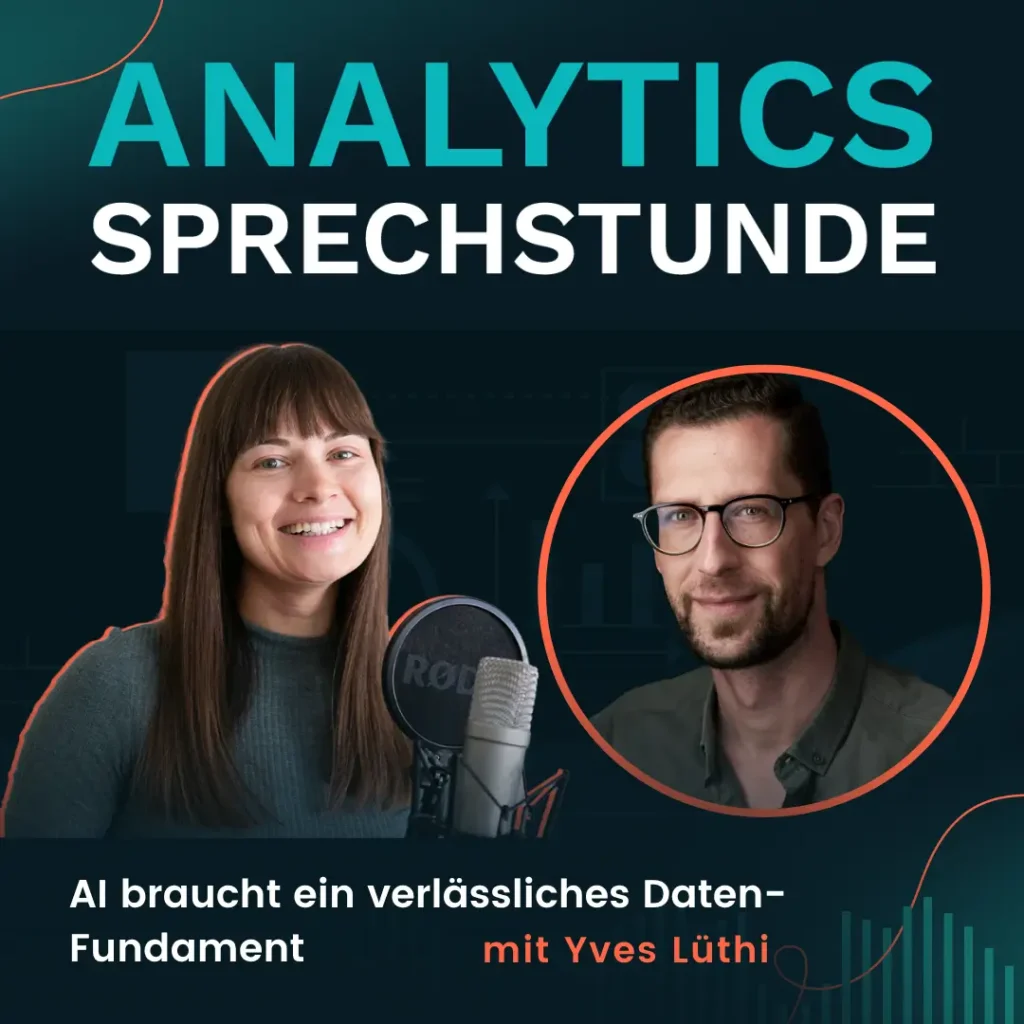
Please note: This episode is in German.
Just recently at OMR, it was celebrated once again: The future of marketing belongs to AI agents and smart automation that open up entirely new levers for us. But for inspiring keynotes to turn into real success in day-to-day business, one crucial detail is needed behind the scenes: an absolutely reliable data foundation.
Without this foundation, my guest warns, there is a risk of “confidence without correctness”—an AI that answers with extreme self-assurance but is built on incomplete logic.
So how do we successfully bridge the gap between big visions and real-world implementation in e-commerce?
We talk about
- how to make the leap from Excel chaos to a reliable single source of truth
- why AI can’t compensate for a messy data foundation—and how a well-prepared infrastructure becomes a true AI enabler
- why data projects aren’t purely IT projects and only create real business value through clear priorities from management
A refreshingly practical episode for anyone who wants to understand what the successful, sustainable path to an AI-powered future really looks like—beyond the pure marketing hype.
Timestamps:
(00:00) Intro and introducing Yves
(03:30) Main discussion: AI & marketing
(24:45) Wrap-up and takeaways for marketing teams
Read the episode transcript
Recorded in German—English translation of the original conversation.
Intro
Maria-Lena Matysik: Hello and a warm welcome to a new episode of Analytics Sprechstunde.
Today my guest is Yves Lüthi. Yves is Head of Tech & Data at X-Technology—the company behind the brands X-Bionic and X-Socks. X-Bionic develops performance equipment for athletes: apparel, accessories and footwear. The products’ users include, among others, professional athletes from elite sports, and last year X-Bionic was also present at the UTMB (Ultra-Trail du Mont-Blanc) in Chamonix—a little fangirl moment for me 😀
In his role, Yves is responsible for the commerce architecture, the ERP and the entire tool landscape around it. At the same time, he drives topics like data architecture, digital transformation and AI adoption within the company.
He describes himself as a translator between the business requirements for the data and the technical implementation. So Yves doesn’t look at data from a purely marketing perspective, but from the systems perspective of a growing e-commerce company.
In this interview, Yves takes me through the status quo of the data architecture at X-Bionic. He then shares his thoughts, requirements and plans for expanding the data infrastructure toward an AI-ready setup.
We also talk about
- why a clean data foundation is more important than any single tool,
- how he and his team got from inconsistent Excel reports to a Single Source of Truth,
- how e-commerce, marketing and tracking data can work together
- and what role AI can (and perhaps should) play in analyzing marketing and customer data.
The episode turned out very hands-on and practical, because Yves shares what it’s really like to bring data, e-commerce and AI together—not as hype along the lines of “Everything’s totally easy, how I built 500 agents in 5 minutes and never have to work again,” but what it’s really like to lay the data foundation for AI.
And with that, on to the interview.
Interview
Maria-Lena Matysik: Hi Yves, it’s a great pleasure to have you on Analytics Sprechstunde today. A warm welcome to my studio—joining us remotely from Switzerland, so to speak.
Yves Lüthi: Exactly, from Zurich. Thank you very much for the invitation, I’m very happy to be here, too. Hello, Maria! I’m really looking forward to our conversation.
Maria-Lena Matysik: The pleasure is all mine.
The focus of this podcast is always on a learning around working with data and insights—and on generating business value from data. So which learning have you brought with you today?
Yves Lüthi: I’d say the learning that fits our topic best today is the topic of the data foundation. In other words: What foundation do you use to analyze data? The whole topic of BI and data analysis—and now, of course, the whole topic of AI as well: How can I use AI to analyze my data better and get to results even faster? At the end of the day, that’s still always based on a good data foundation.
Maria-Lena Matysik: Mhm.
Yves Lüthi: And that takes time. It’s not as if you can simply take a tool, connect it to some system and then expect it to prepare the data the way you’d like it—and, in the best case, also tell you what you should do with it now. Instead, you have to think about the underlying infrastructure and data structure in order to make data-based decisions that are really reliable, that is, ones you can trust. Otherwise, there’s definitely a risk that things go in the wrong direction somewhere. In the AI context, that’s called hallucinating: that it simply isn’t reliable.
The learning really is: It still takes a lot of time to build the data foundation. There’s no way around it. But once you have it, it’s of course much more efficient with today’s tools to make decisions and run reports than it maybe was ten years ago.
Maria-Lena Matysik: Would you maybe walk us through what the starting situation was and how you, or rather you as a team, came up with the idea: Hey, there’s more we can do here, this can be done better, maybe this can be done differently?
Yves Lüthi: Yes, gladly. For that we have to go back a few years—I’d say May 2022, when I started at X-Bionic. You can picture it like this: There wasn’t all that much there in terms of infrastructure and systems. On the one hand, that was of course a huge challenge, but on the other hand, it was also a rewarding starting point for tech people, because you can basically redefine your stack from scratch.
Maria-Lena Matysik: A clean slate.
Yves Lüthi: A clean slate, exactly. You can choose the systems and define the processes, and ultimately it’s up to you how well it all works. You just don’t have all that legacy that you somehow still have to drag along and implement as well.
The starting point back then was actually the implementation of an ERP system. We did that relatively quickly and efficiently, too; we chose Odoo. But we also quickly realized that there was no data transparency. That wasn’t because of the system, but because everyone was somehow pulling their reports out of Odoo. Odoo actually offers a good export tool that lets you pull the data—but what you then do with it is another question.
Maria-Lena Matysik: By data transparency, you mean that everyone on the team is looking at the same data?
Yves Lüthi: Single Source of Truth, exactly. One person pulls the report with these and those fields, another pulls it a little differently—and then you get together in a meeting and suddenly have a different understanding of KPIs like revenue or of how returns are tracked. Then you have discrepancies in your reports, one person calculates it this way and the other that way, and at some point you say: Okay, now we have deviations here again—why?
In the long run, that’s very unsatisfying. Because you also report these numbers upward, to the shareholders and so on, and based on them you also make forecasts, budgets et cetera. If you’re not consistent in data management, in reporting and in the definition of the KPIs, at some point it gets very uncomfortable.
That led us to say: We need a uniform, reliable data foundation. We created it by introducing a BI tool that accesses the ERP data but has this semantic layer in between, which interprets the data and prepares it so that you can easily analyze and read it in the BI tool. That way, everyone actually has the same data foundation and the same interpretation of the data.
Maria-Lena Matysik: Could you maybe make that more tangible with an example? How should we picture what the semantic layer changes?
Yves Lüthi: Imagine you have a huge database in the ERP system. It consists of hundreds of data tables, and that’s where the numbers are. To define a revenue KPI, for example, you first have to establish: What is revenue, how is it calculated and which data fields are relevant for it? Once you’ve done that, the number that comes out is always the same. Then there’s simply one revenue number, and it’s calculated the same way every month.
Maria-Lena Matysik: Mhm.
Yves Lüthi: With the same raw data. And this transformation from the raw data to the final KPI that you report—that’s actually this semantic layer in between.
And if you now imagine that everyone simply exports this raw data via Excel and calculates the revenue KPI in their own Excel file, there’s a high risk that one person takes column C times column F and the other takes column D times column E. Then it’s net one time, gross another time, whatever another time—just not uniform. That alone brought us a lot of peace of mind and trust.
Now you could say: Okay, BI tools already existed ten years ago. Yes, that’s true. Still, for X-Bionic at that point it was extremely central to go in this direction.
And now, of course, comes the next challenge: Okay, now we have the data from the ERP, that’s the core data. How can we now enrich it with third-party data? Let’s say: ad spend, Google Analytics data, user behavior et cetera. You don’t normally have those in the ERP. In the ERP, you have transparency on revenue, margin, customer data, item performance and logistics. As I said, that was fundamental for us. And now the question is: Can we move on to the next stage in order to run further analyses and make decisions that are relevant above all for the D2C area?
That’s where we are right now, I’d say—facing this central architecture question: Do you have one tool for everything? Do you find a way to pull the third-party data into the BI tool as well? Then it gets relatively complex, meaning the data modeling, or rather the semantic layer components, become very complex. Or do you say: No problem, we’ll take a tool that already prepares this data for us and is, for example, Shopify-compatible? The advantage of Shopify is that you have a pretty broad range of apps and systems that work natively with Shopify. And then, for now, you’re fine saying: I have my ERP data in the BI tool, where I track the macro KPIs. And I have a second tool that additionally prepares the third-party data together with the e-commerce data and the customer journey tracking data.
Maria-Lena Matysik: So what are your thoughts on that—which poison do you ultimately have to pick there?
Yves Lüthi: You have to pick one, exactly. My tendency is to say: At this point in time, we can easily work with two tools, because this data doesn’t necessarily have to be combined in one system.
Maria-Lena Matysik: Because the complexity would also simply become very high.
Yves Lüthi: The complexity becomes enormous. On the one hand, you can say: I take the data from Shopify and the third-party tools and try to bring it into the ERP BI tool via a connector—or manually once a month, which wouldn’t be a clean solution either. But there you first have to prepare this data all over again. You don’t send it directly to the BI; you store it somewhere in the data warehouse and then have to prepare it in the BI layer, that is, make it visualizable.
Or you go the other way and ask: Which data from the ERP do I absolutely need on the other side, too? That’s usually much less, because all the transaction data and customer data from Shopify is already there anyway. But you have the advantage that these tools prepare the third-party data and also the marketing spend in a way that lets you build your KPIs from it.
So I tend toward a two-track approach. That’s definitely defensible—with the advantage that this topic of the Semantic Layer, meaning this abstraction layer between the raw data and the end user, simply works cleanly. And once you have that, you can also start running data analyses with AI. Because if you unleash AI directly on the raw data, there’s a risk of misinterpretations. AI does recognize the data and can perhaps even interpret it intelligently to a certain degree, but you simply run the risk of hallucinations somewhere. And then that can definitely lead to fatal wrong decisions if you rely on it alone.
I think nowadays there really are tools out there that would create huge added value for us and that connect natively with AI—Claude, ChatGPT, whatever. And this dream—I just type my question into my AI tool, and the tool spits out the answer, including three recommendations for how I can optimize my margin through which channel or which customer segment and which campaign I’d best create right away for it, which in the best case is then even fed automatically into the email marketing tool—that’s actually not that far off anymore.
Maria-Lena Matysik: Mhm.
Yves Lüthi: That’s possible if you have this clean data foundation. Building that yourself in-house now and bringing it into the BI tool is, as I said, something I consider very complex—unless you have a huge data team that does it for you. But given how we’re set up, the right way would be to take this two-track approach, rely on third-party tools that can do exactly that, and then create added value with AI.
Maria-Lena Matysik: And do you already have ideas for how you would connect AI to the data? Is the idea, for example, to use a Claude interface, and Claude can then access either one data source or the other?
Yves Lüthi: Exactly, that’s roughly how I’d picture it. Specifically: We have the ERP data in our Superset BI. You can connect to it via MCP, that is, connect Claude to the BI via MCP.
And on the other side, we’d have Shopify with its app environment and a dedicated BI or data tool on top. That could be, for example, Polar Analytics, which I’m very interested in at the moment. At the end of the day, they offer exactly the same function: You connect it to Claude and can then run your data analyses via Claude. Then you can still consider whether you want to connect the two sources again in Claude to generate aggregated datasets—although I think that won’t necessarily even be needed.
And the next step would then really be this data—and that’s where you come in, of course, with all the tracking data that we’re implementing in Shopify together with you. That’s actually what provides the added value on top of the pure transaction and customer data in Shopify. Then you can say exactly: Okay, generate customer segments for me from customers who triggered this and that event on the website, that is, who performed this and that action on the website. Generate a segment from that and suggest a campaign for how I can turn them into Returning Buyers.
And then of course it would be fantastic if you also connected that directly to Klaviyo and Klaviyo generated this email campaign for you with the data that ended up in Claude from the tool. That’s what we want to work toward, that’s the vision right now. And I think we’ve now created the foundation for it.
Now it’s about, on the one hand, implementing the tracking data in the D2C area at such a granular level that we can actually do these analyses. And on the other hand, choosing the tool that gives us this transparency—and, at the end of the day, also the automation via the Claude MCP connector, so that we can run these reliable analyses.
Maria-Lena Matysik: Do you have some kind of timeline for that? Do you think it’s a process that will still take quite a while? Or do you work in a way where you say: Hey, we’re now building an MVP for the first use case? Maybe you can share a bit about how you see it in terms of timing.
Yves Lüthi: The tool decision is on the table now, no question. In my experience, tools like that—I’m referring to Shopify now—that connect natively with Shopify are relatively easy to implement. People always talk about plug-and-play; it ends up being a bit more than that, but as a rule, setting it up goes relatively quickly. In that respect, I think it’s realistic to run pilots within the next six months.
What you mustn’t forget with this whole topic: We’re talking here together, we both have a tech understanding and are probably also very advanced power users when it comes to AI, or whatever you want to call it. But of course you have a company, and this digital transformation, this AI adoption that I mentioned at the beginning, can then slow things down a bit at times. On the one hand, people first have to trust the tools, and on the other hand, they still have to learn how to work with them efficiently.
That’s actually where I see the big challenge for us, too: that we now quickly take this adoption to the next level. Because the development in the field of AI is really crazy. There’s basically a release somewhere every day, a launch of something new, and every day you think: Darn, I’m already a month late again. And at the same time, you have the challenge: How do I bring the team along on the journey? How do I make sure everyone comes along? That can then slow down the roadmap a bit again, too.
But in principle, I actually believe that something like this is definitely realistic in three to six months if you put a focus on it—if not even faster. In that respect, I’d say: The goal would be to be far enough along in six months that we can use this by means of AI.
Maria-Lena Matysik: Great, then you’ll get an email from me in six months for a podcast follow-up episode.
Yves Lüthi: Follow-up podcast, gladly. Maybe we’ll postpone it then, too—who knows what will happen. But no, I actually see this as realistic.
Maria-Lena Matysik: Would you maybe derive and summarize your learnings from all these considerations, thoughts and trade-offs once more?
Yves Lüthi: Yes, gladly. I think the most important learning—for us, but also in general—is that AI can’t replace a clean data foundation. At least not as of today. I think AI is an enabler; it empowers what lies beneath it. Because it simply lets you work much faster and much better—all that tinkering with Excel formulas is simply history if you use it right. If the data is good and the data foundation is correct, AI has huge leverage in this area, no question.
But if that isn’t the case, it becomes rather dangerous, because then wrong conclusions can be drawn that sound very convincing. And you run the risk of trusting blindly and thinking: Okay, the AI told me this, I’ll do it this way now, done. That’s where I see the big challenge. How can you put it: Confidence without correctness is the big risk. That’s generally the case, even when you only use AI as a chat: What comes back is extremely self-assured every time. And if you want to believe it, then that’s how it is. You really have to be careful there, especially with data topics.
The second learning: The choice of tool is very important, but at the end of the day still secondary. Because what’s ultimately decisive is the data logic and the architecture underneath. If you simply buy a tool and only afterward think about how you want to measure what, then you’re building on sand, so to speak. That just won’t hold.
And the third learning: At the end of the day, the target picture really has to be that you can somehow connect reporting, marketing data and user behavior to get the full picture. If you look at it in complete isolation, at some point it gets difficult. You have to find a way to link the data, at least to some extent, so that you can then run truly reliable and profitable analyses.
Maria-Lena Matysik: Mhm.
Yves Lüthi: Those are more or less the three main learnings, I’d say.
Maria-Lena Matysik: Exciting. I have one final question—thought a bit more operationally, so a little closer to the ground: What would you say you’ve learned in recent months that you could pass on to others so they don’t have to learn it the hard way themselves? So how you started this process and where, in hindsight, you think: If I’d done that differently, it might have gone faster.
Yves Lüthi: I actually think it still starts with how you define processes. You have to understand your processes first before you can measure anything. I remember it well: When we introduced the ERP back then, we were a completely new team. The company had existed for 25 years, but there was a lot we didn’t know back then. We implemented an ERP quickly, which was extremely important for us operationally. But we only understood many processes over time and then partly had to adjust them again. That’s where you run the risk of doing things two or three times.
That means: a clean process analysis, combined with a clean data analysis. And if we break it down to tracking—since today we’re also talking with you at Analyticsfreaks—then it’s ultimately the same: You have a target picture somewhere, you want to measure something. And then often a bit of time gets lost, or you don’t want to invest the time to analyze cleanly: What does this thing I want to measure here actually mean, and which data do I have to track to be able to measure this KPI reliably?
So I’d say: Better to invest a bit more time and also money in order to be much more efficient down the line and not have to touch and change the whole thing two, three, four more times. I think a lot of people make that mistake. We make it every now and then, too. Often it’s time pressure where you just say: Okay, let’s do it quickly, quickly, quickly. But if you take a little more time, invest two or three more hours to understand once more what exactly is needed—also together with the developers—then at the end of the day you have a better and more satisfying result.
A second learning that can help is the topic of expectations versus reality—and the scope that follows from that. The expectation is: I want to measure everything right away. The reality is: We can’t, we don’t have it yet. And from that, the task is to define a scope that’s realistic. Because if you keep defining a scope you can’t achieve, it gets frustrating. Better to cut the topics into small pieces, run an agile model and say: Okay, we’re only doing this now, but we’re doing it right. Then we celebrate the fact that it worked and tackle the next thing. Because if you put the cart before the horse, it just becomes frustrating for everyone.
Maria-Lena Matysik: I think that’s a super, super valuable learning.
Yves Lüthi: And as I said, I make that mistake myself every now and then, too, thinking: Oh come on, let’s just quickly do this now.
Maria-Lena Matysik: I think we all want everything right away and perfect, the target picture and the vision—and not to wait so long.
Yves Lüthi: Yes. And at the end of the day, also involve management. Ask very specific questions—without getting too technical under any circumstances, but simply asking: Okay, what do you want to measure? What are the three most important topics that are relevant for you right now? Where can we bring in transparency? Define the scope from that, deliver and then ask the same question again. Then, I think, you make progress, everyone sees the progress and everyone is somehow satisfied.
In any case, much more so than if you write down 50 KPIs and say all of this has to be measured, and ultimately come back with ten and think: Okay, now we’ve somehow achieved 20 percent of what we should have achieved. In the long run, that’s simply no fun.
Maria-Lena Matysik: Yves, thank you so, so much. The half hour went by incredibly fast, I really have to say. Thank you so much for all the insights. I found it super, super exciting. Thanks for sharing!
Yves Lüthi: My pleasure. Thank you very much for the invitation, it was fun. See you in six months! Thanks, Maria.
Maria-Lena Matysik: The follow-up will come then. Exactly, see you in six months. Thank you!
Outro
Maria-Lena Matysik: What I took away from this conversation is, for one, the process perspective in the ongoing development of an architecture. For example, that management and business departments have to be involved early—and that it’s better to implement a few use cases or KPIs cleanly than too many only halfway.
Because data projects are not purely technical projects. One central question should always be: What are the most important topics for which we need transparency through data right now? When management and business departments provide these priorities, the scope becomes clearer, the implementation more realistic—and only then does real value from the data for the business become possible.
Especially in marketing and e-commerce, the desire to be able to measure everything right away is often strong—because you can, after all, measure a great deal. But the learning from this episode is very clear here: Better to start with the most important questions, cut the scope realistically and implement individual topics cleanly—instead of starting with 50 KPIs and in the end only being able to use a fraction of them truly reliably. And that also includes clean expectation management: not promising stakeholders a wonderful new world of AI, but naming clear use cases and questions that are to be solved afterward.
And the last learning I’d like to pick up on again here: AI doesn’t replace a clean data foundation.
Personally, I find it interesting that Yves emphasized this so explicitly. Because I’m often asked whether we, as a specialized analytics agency, won’t soon become superfluous because in the age of AI you supposedly don’t need analytics experts anymore.
Yves’ statement on this was—and I see it exactly the same way—that AI can speed up analyses, make connections visible and, going forward, also deliver recommendations for campaigns. But AI only becomes truly helpful when the underlying data is meaningful, cleanly structured and consistently defined, has the right context, and so on, and so on… Otherwise, you may get very convincing-sounding but potentially wrong, hallucinated results.